公众号旧文
我的 YouTube 下载站,第一次被自然访问了
最近一直在 Anti Content Theft,都没怎么鼓捣服务器了。
https://github.com/pangzibaike/anti-content-theft刚打开流量统计才发现,这几天下载机的流量有了异常增长。
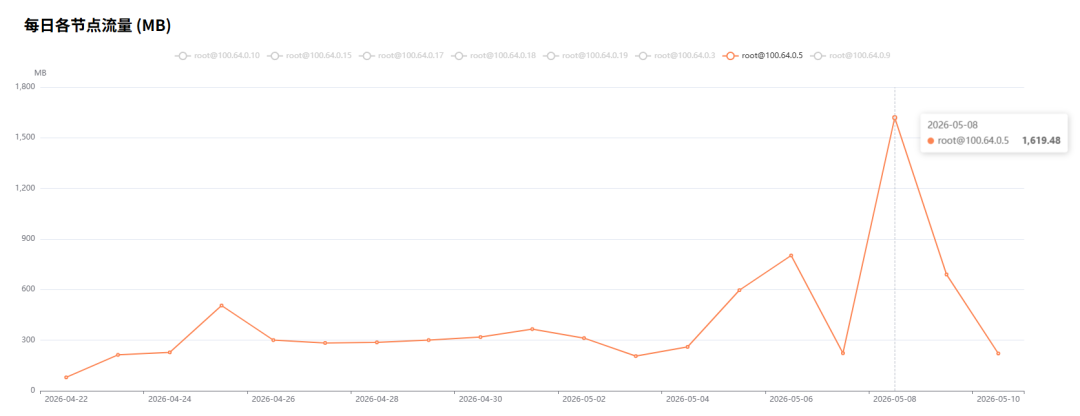
比如 5 月 6 日、5 月 8 日,都出现了与平日极为不同的流量消耗。
于是我开始在所有 nginx 日志里筛选。
最后,还真让我筛出了几个真实用户 IP。
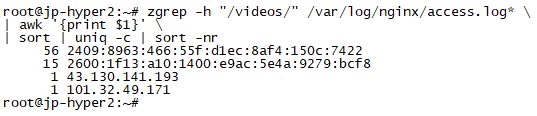
第一名下载了接近 500MB 的视频。

请求非常规律。
先提交任务:
POST /task随后不断轮询:
GET /status/xxx最后开始下载:
GET /videos/xxx.mp4跑完了整个下载流程。
还能从 User-Agent 里看出来,对方用的是 HarmonyOS 手机。
Mozilla/5.0 (Linux; Android 12; HarmonyOS; ADY-AL00)也就是说,真的有陌生人,用手机访问了我做的下载站。
后端日志里,还记录了用户提交的 YouTube 视频链接。
因为 yt-dlp 下载时,会输出 Extracting URL
于是我直接开始翻 journalctl -u ytdlp
就把用户提交过的视频链接全统计出来了。
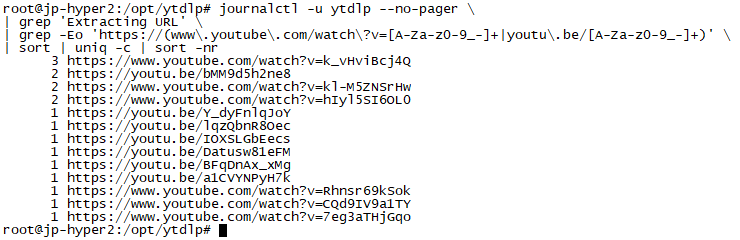
第一名用的是手机,上图中的短链,显然就是他下载的那些视频。
第二名用的电脑,UA如下:
Mozilla/5.0 (Windows NT 10.0; Win64; x64)
Chrome/147
他俩一个看的日本男团,一个看的英国纪录片。
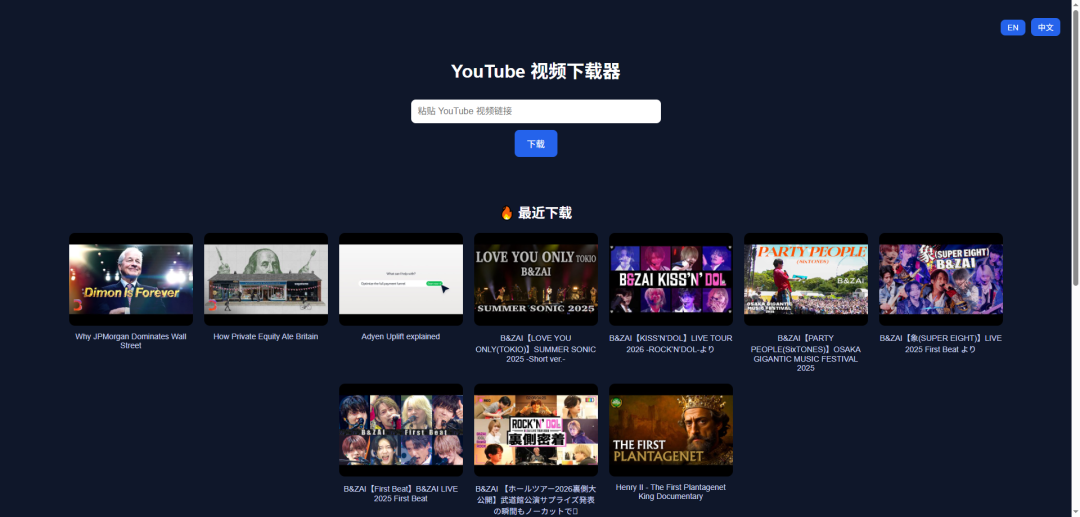
我建站的目的,一方面是机器闲着也是闲着,一方面是想看看大家都对什么内容感兴趣,用大家感兴趣的视频,来拓宽一下我自己的视野。
最后分享一下项目结构:
/opt/ytdlp
├── server.py        后端 Flask 服务
├── index.html       前端页面
├── yt-dlp           下载核心程序
├── cookies.txt      YouTube cookies
├── videos/          临时视频文件目录
├── venv/            Python 虚拟环境
└── gunicorn.ctl     gunicorn 启动配置
再分享一下代码:
/opt/ytdlp/server.py

from flask import Flask, request, jsonify, send_file, send_from_directory
import os
import uuid
import subprocess
import threading
import time
import shutil
import re

app = Flask(__name__)

VIDEO_DIR = "videos"
YTDLP = "/opt/ytdlp/yt-dlp"

FILE_EXPIRE = 3600  # 1小时删除
MIN_FREE_SPACE = 1024 * 1024 * 1024  # 最少需要1GB空闲

TASKS = {}
DOWNLOADING = False

if not os.path.exists(VIDEO_DIR):
    os.makedirs(VIDEO_DIR)


@app.route("/")
def home():
    return send_file("index.html")


# 检查磁盘空间
def check_disk_space():

    total, used, free = shutil.disk_usage("/")

    if free < MIN_FREE_SPACE:
        return False

    return True


# 创建任务
@app.route("/task", methods=["POST"])
def create_task():

    cleanup_once()

    global DOWNLOADING

    data = request.json
    url = data.get("url")

    if not url:
        return jsonify({"error": "no url"})

    if "youtube.com" not in url and "youtu.be" not in url:
        return jsonify({"error": "invalid url"})

    if DOWNLOADING:
        return jsonify({
            "error": "busy",
            "message": "当前已经有下载任务正在进行"
        })

    if not check_disk_space():
        return jsonify({
            "error": "disk_full",
            "message": "服务器磁盘空间不足"
        })

    task_id = str(uuid.uuid4())

    TASKS[task_id] = {
        "status": "downloading",
        "file": None,
        "time": time.time()
    }

    DOWNLOADING = True

    thread = threading.Thread(target=download_video, args=(task_id, url))
    thread.daemon = True
    thread.start()

    return jsonify({"task": task_id})


# 查询任务
@app.route("/status/<task_id>")
def task_status(task_id):

    task = TASKS.get(task_id)

    if not task:
        return jsonify({"error": "task not found"})

    return jsonify(task)


# 下载视频
def download_video(task_id, url):

    global DOWNLOADING

    try:

        output = f"{VIDEO_DIR}/{task_id}.%(ext)s"

        cmd = [
            YTDLP,
            "--js-runtimes", "node",
            "--no-playlist",
            "--concurrent-fragments", "3",
            "--throttled-rate", "100K",
            "-f bv*+ba/b",
            "--merge-output-format", "mp4",
            "-o", output,
            url
        ]

        subprocess.run(cmd, check=True)

        TASKS[task_id]["status"] = "finished"
        for file in os.listdir(VIDEO_DIR):
            if file.startswith(task_id):
                TASKS[task_id]["file"] = file

    except Exception as e:

        TASKS[task_id]["status"] = "error"
        TASKS[task_id]["error"] = str(e)

    finally:

        DOWNLOADING = False


# 下载文件
@app.route("/videos/<path:filename>")
def videos(filename):
    return send_from_directory(VIDEO_DIR, filename)


if __name__ == "__main__":

    app.run(host="0.0.0.0", port=5001)

def cleanup_once():

    now = time.time()

    for file in os.listdir(VIDEO_DIR):

        path = os.path.join(VIDEO_DIR, file)

        if os.path.isfile(path):

            if now - os.path.getmtime(path) > FILE_EXPIRE:
                os.remove(path)

@app.route("/recent")
def recent_downloads():

    try:

        result = subprocess.check_output(
            "journalctl -u ytdlp -n 200 | grep 'Extracting URL'",
            shell=True
        ).decode()

        videos = []

        for line in result.splitlines():

            m = re.search(r'(https://www\.youtube\.com/watch\?v=[\w-]+|https://youtu\.be/[\w-]+)', line)

            if m:
                videos.append(m.group(0))

        # 去重并保留顺序
        seen = set()
        unique = []

        for v in videos[::-1]:
            if v not in seen:
                unique.append(v)
                seen.add(v)

        return jsonify(unique[:10])

    except Exception:
        return jsonify([])
扩展阅读: